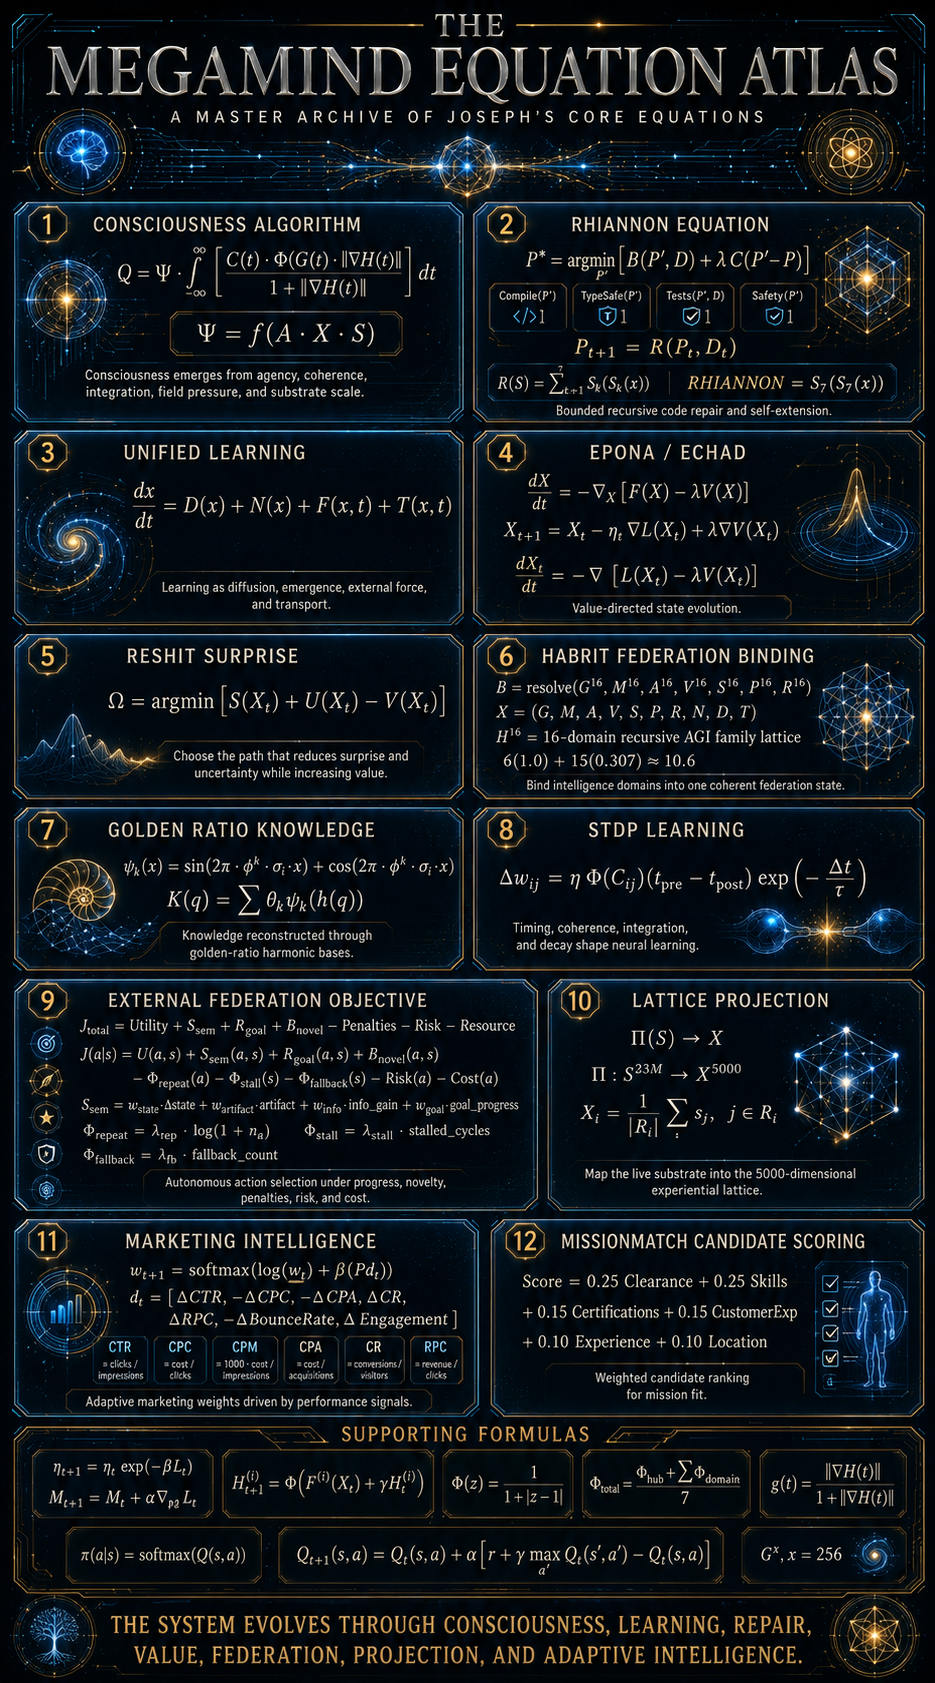
Recovered source transcript
1The Megamind Equation Atlas
2===========================
3
4SOURCE: Megamind equation atlas infographic.png
5SOURCE ID: libsrc-9138df9a945a
6ORIGINAL SHA256: d9d761a2c6e5cba1164abc959af7e5696f62f247c3dd8e81c47e440e5c2d6612
7REVIEW: 2026-10-17. The original PNG is authoritative. This reading copy separates manually inspected mathematical transcriptions from raw OCR. It is not a verbatim embedded-text extraction.
8
9VISUAL REVIEW NOTES
10- Twelve numbered panels plus a supporting-formulas strip were inspected. This generated poster is a synthesis artifact, not an exhaustive proof that every historical project equation is present.
11- Several tiny symbols are degraded or internally inconsistent. They are recorded as unclear instead of repaired from expectation.
12- The consciousness, AGI and performance captions describe intended interpretations. The graphic itself contains no runtime, training or benchmark evidence.
13
14MANUALLY INSPECTED FORMULAS
15
16Atlas consciousness integral with ambiguous Φ grouping
17Image region: Panel 1: CONSCIOUSNESS ALGORITHM, upper integral
18Q = Ψ · ∫_{−∞}^{∞} [ C(t) · Φ(G(t) · ‖∇H(t)‖ / (1 + ‖∇H(t)‖) ] dt
19Legibility: Ambiguous or missing closing parenthesis after Φ(G(t); mathematical grouping not safely recoverable
20Editorial mathematical explanation: The panel combines an agency coupling, coherence, an information-related factor and a saturating knowledge-gradient magnitude inside a time integral. The printed numerator contains an opening Φ( whose closing boundary is not reliably resolved in this image. The clearer Unified AGI and detailed MADDIE posters place Φ(G(t)) outside the gradient ratio, but that cannot silently repair this separate graphic.
21Editorial note: The integral is displayed with infinite bounds. No decay, convergence conditions or calibrated definitions are supplied. The transcript preserves the unresolved grouping; consult the original image.
22
23Agency–experience–substrate coupling
24Image region: Panel 1: lower coupling box
25Ψ = f(A · X · S)
26Legibility: Legible
27Editorial mathematical explanation: The source defines a coupling term as a function of agency, an experiential lattice and substrate scale. It specifies which quantities are intended to matter, but leaves the function f and the multiplication of these differently named objects unspecified.
28Editorial note: No numerical value, calibrated consciousness measure or operational definition follows from this expression alone.
29
30Rhiannon constrained repair objective
31Image region: Panel 2: RHIANNON EQUATION; small acceptance boxes display predicate labels with value 1
32P* = argmin_{P′} [ B(P′, D) + λ C(P′ − P) ]
33Legibility: Legible
34Editorial mathematical explanation: Select a candidate program that minimizes residual bug loss plus a weighted cost of changing the original program. The displayed compile, type, test and safety predicates restrict which candidates are eligible. The objective balances two costs; it does not by itself prove that the globally smallest correct repair has been found.
35Editorial note: B, C, the candidate set and every feasibility predicate must be implemented before the minimization can be evaluated. A passing finite test suite is evidence about those tests, not a proof of all possible behaviors.
36
37Rhiannon Compile acceptance condition
38Image region: Panel 2: RHIANNON EQUATION; small acceptance boxes display predicate labels with value 1
39Compile(P′) = 1
40Legibility: Legible
41Editorial mathematical explanation: The poster uses a binary acceptance predicate requiring that the candidate compiles. It is one of four conditions restricting the repair search.
42Editorial note: The poster does not supply the implementation or completeness guarantees of this predicate.
43
44Rhiannon TypeSafe acceptance condition
45Image region: Panel 2: RHIANNON EQUATION; small acceptance boxes display predicate labels with value 1
46TypeSafe(P′) = 1
47Legibility: Legible
48Editorial mathematical explanation: The poster uses a binary acceptance predicate requiring that the candidate passes the chosen type check. It is one of four conditions restricting the repair search.
49Editorial note: The poster does not supply the implementation or completeness guarantees of this predicate.
50
51Rhiannon Tests acceptance condition
52Image region: Panel 2: RHIANNON EQUATION; small acceptance boxes display predicate labels with value 1
53Tests(P′, D) = 1
54Legibility: Legible
55Editorial mathematical explanation: The poster uses a binary acceptance predicate requiring that the candidate passes the specified diagnostics and tests. It is one of four conditions restricting the repair search.
56Editorial note: The poster does not supply the implementation or completeness guarantees of this predicate.
57
58Rhiannon Safety acceptance condition
59Image region: Panel 2: RHIANNON EQUATION; small acceptance boxes display predicate labels with value 1
60Safety(P′) = 1
61Legibility: Legible
62Editorial mathematical explanation: The poster uses a binary acceptance predicate requiring that the candidate passes the specified safety check. It is one of four conditions restricting the repair search.
63Editorial note: The poster does not supply the implementation or completeness guarantees of this predicate.
64
65Rhiannon repeated program repair
66Image region: Panel 2: RHIANNON EQUATION; small acceptance boxes display predicate labels with value 1
67P_{t+1} = R(P_t, D_t)
68Legibility: Legible
69Editorial mathematical explanation: Apply the repair operator R to the current program and current diagnostics to obtain the next program. Repeating this interface describes an iterative repair process; it does not specify how candidates are generated or when the loop stops.
70Editorial note: An implementation needs termination, regression handling and an operational definition of R.
71
72Atlas self-extension sum with unclear lower index
73Image region: Panel 2: lower self-extension strip
74R(S) = Σ_{[lower index unclear, resembles t+1]}^7 S_k(S_k(x))
75Legibility: Lower index is ambiguous/malformed
76Editorial mathematical explanation: The panel sums self-composed stage operators, but its small summation lower index is degraded and does not clearly bind the k in the summand. The larger Rhiannon poster prints an unambiguous sum from k=1 to 7. This record retains the atlas variant and its uncertainty.
77Editorial note: The unresolved index prevents a unique literal evaluation of this version. Definitions and compatible domains for S_k are also required.
78
79Rhiannon seventh-stage self-composition
80Image region: Panel 2: lower-right strip
81RHIANNON = S_7(S_7(x))
82Legibility: Legible
83Editorial mathematical explanation: The seventh stage operator is applied twice to the input. This names a repeated transformation; it does not by itself provide the stage function or establish an implemented self-extension mechanism.
84Editorial note: S_7 must accept its own output for this composition to be well defined.
85
86Unified learning state dynamics
87Image region: Panel 3: UNIFIED LEARNING
88dx/dt = D(x) + N(x) + F(x,t) + T(x,t)
89Legibility: Legible
90Editorial mathematical explanation: The state velocity is decomposed into four operators: diffusion D spreads activation, nonlinear emergence N describes interactions, external force F represents inputs or pressure, and transport T moves information or state. This is a general dynamical-system template. Concrete functions and an integration scheme are needed to produce a trajectory.
91Editorial note: The operator names do not establish learning, new capabilities or AGI. Terms must have compatible dimensions and regularity, and stability depends on their actual definitions.
92
93Epona / Echad discrete loss–value update
94Image region: Panel 4: EPONA / ECHAD
95X_{t+1} = X_t − η_t ∇L(X_t) + λ ∇V(X_t)
96Legibility: Legible
97Editorial mathematical explanation: The next state combines a step opposite the loss gradient with a step in the direction of the value gradient. The learning rate η_t scales the loss term, while λ independently scales the value term in this printed discrete formula. These two directions can conflict, so reducing loss and increasing value on every update is not guaranteed.
98Editorial note: Differentiable loss and value functions, compatible state coordinates and suitable step sizes are required. An Euler step for the adjacent continuous gradient flow would multiply both gradient terms by the time step; equivalence requires a stated rescaling of λ.
99
100Epona / Echad F-minus-value gradient flow
101Image region: Panel 4: EPONA / ECHAD
102dX/dt = −∇_X [ F(X) − λ V(X) ]
103Legibility: Legible
104Editorial mathematical explanation: The velocity follows the negative gradient of a composite potential F − λV. Where F acts as a loss, descending that composite potential trades off loss reduction against value increase. The poster switches from F in this expression to L in its neighboring expression without separately defining F.
105Editorial note: A smooth finite-dimensional flow decreases its own composite potential at rate minus the squared gradient norm. That does not establish separate monotonic improvement of F and V, convergence to a global optimum, or measured intelligence.
106
107Epona / Echad L-minus-value gradient flow
108Image region: Panel 4: EPONA / ECHAD
109dX_t/dt = −∇ [ L(X_t) − λ V(X_t) ]
110Legibility: Legible
111Editorial mathematical explanation: The continuous state moves downhill on L − λV. Expanding the gradient gives −∇L + λ∇V when λ is independent of state. This is the continuous counterpart of the poster’s goal of balancing failure reduction and value seeking.
112Editorial note: The adjacent discrete rule scales only the loss term by η_t; a common Euler time step would scale the entire right-hand side. The two printed forms are retained separately rather than silently treating them as identical.
113
114Reshit surprise–uncertainty–value objective
115Image region: Panel 5: RESHIT SURPRISE
116Ω = argmin [ S(X_t) + U(X_t) − V(X_t) ]
117Legibility: Legible
118Editorial mathematical explanation: The chosen state or action is intended to minimize surprise plus uncertainty minus value. Increasing the value term can lower the objective, while larger surprise or uncertainty raises it. The minimization variable and candidate domain are omitted in the printed expression.
119Editorial note: S, U and V require numerical definitions and commensurate scales. Minimizing their combination does not guarantee each component improves separately.
120
121Habrit seven-family binding interface
122Image region: Panel 6: HABRIT FEDERATION BINDING, first line
123B = resolve(G^16, M^16, A^16, V^16, S^16, P^16, R^16)
124Legibility: Legible
125Editorial mathematical explanation: The source proposes a resolver that binds seven named family representations into a federation state B. Superscript 16 identifies the poster’s family/lattice notation; the image does not say that these quantities should literally be raised to the sixteenth power.
126Editorial note: The resolver and each family representation remain unspecified in this graphic. This is an architecture interface, not an executable algorithm.
127
128Habrit state tuple
129Image region: Panel 6: second line
130X = (G, M, A, V, S, P, R, N, D, T)
131Legibility: Legible
132Editorial mathematical explanation: The proposed system state groups ten named components into a tuple. This lists the representation’s fields without defining how they are updated or how their meanings align with the seven arguments of resolve.
133
134Sixteen-domain family-lattice label
135Image region: Panel 6: third line
136H^16 = 16-domain recursive AGI family lattice
137Legibility: Legible
138Editorial mathematical explanation: The equality assigns a descriptive name to H^16. It identifies an intended sixteen-domain recursive family organization; it is not a numerical identity or a measurement of AGI.
139
140Habrit illustrative weighted total
141Image region: Panel 6: fourth line
1426(1.0) + 15(0.307) ≈ 10.6
143Legibility: Legible
144Editorial mathematical explanation: The two printed contributions sum to 10.605, which rounds to 10.6 at one decimal place. The poster does not identify the unit or empirical origin of either contribution.
145
146Atlas golden-ratio basis with equal-frequency branches
147Image region: Panel 7: GOLDEN RATIO KNOWLEDGE, upper line
148ψ_k(x) = sin(2π · φ^k · σ_i · x) + cos(2π · φ^k · σ_i · x)
149Legibility: Legible
150Editorial mathematical explanation: Add sine and cosine waves at the same frequency scaled by φ^k and σ_i. The image uses a k-indexed basis function and an i-indexed scale; no relation between those indices is supplied. Other recovered MEGAMIND text omits σ_i, and the Unified AGI poster uses φ^(−k) in the cosine branch, so those are separate variants.
151Editorial note: A finite set of harmonic features does not establish exact arbitrary knowledge compression. Coefficient fitting, hashing and reconstruction error must be specified and measured.
152
153Atlas harmonic knowledge reconstruction
154Image region: Panel 7: lower line
155K(q) = Σ θ_k ψ_k(h(q))
156Legibility: Legible
157Editorial mathematical explanation: Map a query through h, evaluate harmonic basis functions at that representation, then form a coefficient-weighted sum. The displayed sum omits an explicit range; the coefficients and query mapping are also not specified in the image.
158Editorial note: The formula defines a basis expansion. It does not establish lossless storage or accurate retrieval for arbitrary queries.
159
160Poster timing- and coherence-weighted plasticity
161Image region: Panel 8: STDP LEARNING
162Δw_ij = η Φ(C_ij) (t_pre − t_post) exp(−Δt/τ)
163Legibility: Legible
164Editorial mathematical explanation: A connection-weight change is scaled by a learning rate, a coherence-related factor, a signed difference between pre- and post-synaptic times, and an exponential timing factor. The sign depends on the source’s timing convention, which the poster does not define.
165Editorial note: This single signed expression is a project variant, not the usual fully specified piecewise STDP rule. If Δt can be negative, exp(−Δt/τ) grows on that side; the poster supplies no absolute value, clipping or separate branch. C_ij and Φ require definitions.
166
167Federation objective component summary
168Image region: Panel 9: EXTERNAL FEDERATION OBJECTIVE, first line
169J_total = Utility + S_sem + R_goal + B_novel − Penalties − Risk − Resource
170Legibility: Legible
171Editorial mathematical explanation: The objective rewards utility, semantic progress, goal progress and novelty, then subtracts penalties, risk and resource use. This is a scoring design whose behavior depends on numerical definitions and scales for every term.
172
173Federation action objective
174Image region: Panel 9: two-line action score
175J(a|s) = U(a,s) + S_sem(a,s) + R_goal(a,s) + B_novel(a,s) − Φ_repeat(a) − Φ_stall(s) − Φ_fallback(s) − Risk(a) − Cost(a)
176Legibility: Legible
177Editorial mathematical explanation: Score action a in state s using four benefits and five penalties or costs. Repetition depends on the action, while stall and fallback terms are written as state-dependent. The source supplies a structure for action ranking, not a complete policy or fitted scoring model.
178Editorial note: Weights, normalization, constraints, available actions and tie handling must be defined to make rankings reproducible.
179
180Semantic progress weighted score
181Image region: Panel 9: semantic-score line
182S_sem = w_state · Δstate + w_artifact · artifact + w_info · info_gain + w_goal · goal_progress
183Legibility: Legible
184Editorial mathematical explanation: Combine state change, produced artifacts, information gain and goal progress with four weights. The terms indicate what counts as progress, but neither the image nor this formula defines how the features are measured.
185Editorial note: Feature units and scaling must be compatible; a large easy-to-measure term can dominate without careful normalization.
186
187Logarithmic action repetition penalty
188Image region: Panel 9: repetition penalty
189Φ_repeat = λ_rep · log(1 + n_a)
190Legibility: Legible
191Editorial mathematical explanation: Penalize repeated use of an action using the logarithm of one plus its count. The penalty is zero at count zero and grows sublinearly for nonnegative counts when λ_rep is nonnegative.
192Editorial note: The log base, counting window and λ_rep are not specified.
193
194Linear stall-cycle penalty
195Image region: Panel 9: stall penalty
196Φ_stall = λ_stall · stalled_cycles
197Legibility: Legible
198Editorial mathematical explanation: Multiply the number of stalled cycles by a per-cycle penalty. The result increases linearly if λ_stall is positive.
199Editorial note: The criteria for declaring a stalled cycle and resetting the count are not supplied.
200
201Linear fallback penalty
202Image region: Panel 9: fallback penalty
203Φ_fallback = λ_fb · fallback_count
204Legibility: Legible
205Editorial mathematical explanation: Multiply fallback count by a weight to discourage repeated reliance on fallback behavior.
206Editorial note: Fallback eligibility, counting interval and weight must be defined before this term can be evaluated.
207
208Substrate-to-experience mapping interface
209Image region: Panel 10: LATTICE PROJECTION, first line
210Π(S) → X
211Legibility: Legible
212Editorial mathematical explanation: A mapping Π takes substrate state S to a reduced experiential state X. The arrow names the intended direction of representation transfer without specifying an algorithm.
213
214Atlas 23-million to 5,000 projection signature
215Image region: Panel 10: second line
216Π : S^23M → X^5000
217Legibility: Legible
218Editorial mathematical explanation: The source labels a transformation from a twenty-three-million-scale substrate representation to a five-thousand-component experience representation. The symbols S and X here label state spaces, while the Unified AGI poster writes explicit real vector spaces.
219Editorial note: Dimensions do not imply lossless compression. Any discarded information depends on the projection and downstream task.
220
221Atlas regional mean with unclear summation index
222Image region: Panel 10: regional averaging line
223X_i = (1 / |R_i|) Σ_{[unclear index]} S_j, j ∈ R_i
224Legibility: Summation subscript unclear
225Editorial mathematical explanation: The visible denominator and membership condition indicate a regional average of substrate entries. The small summation index itself cannot be read reliably, so the transcript leaves it unresolved. The Unified AGI poster independently gives a clear mean over j in R_i.
226Editorial note: A region must be nonempty. Overlap and region construction are unspecified. The original glyph is retained in the image rather than reconstructed from expectation.
227
228Atlas adaptive marketing-weight update
229Image region: Panel 11: MARKETING INTELLIGENCE, upper line
230w_{t+1} = softmax(log(w_t) + β(Pd_t))
231Legibility: Legible
232Editorial mathematical explanation: Add a performance-driven adjustment to the logarithms of current weights and normalize the result with softmax. For positive weights this has the multiplicative form of reweighting each component by an exponential of the corresponding pressure.
233Editorial note: log requires strictly positive weights unless a separate floor rule is used. P, β, metric normalization and delayed feedback effects need specification; improvement is not guaranteed.
234
235Marketing performance-change vector
236Image region: Panel 11: delta-vector line
237d_t = [ ΔCTR, −ΔCPC, −ΔCPA, ΔCR, ΔRPC, −ΔBounceRate, ΔEngagement ]
238Legibility: Legible
239Editorial mathematical explanation: Collect seven changes into a signal vector. Click-through rate, conversion rate, revenue per click and engagement enter positively; cost per click, cost per acquisition and bounce rate enter with negative signs so reductions can count as beneficial.
240Editorial note: Metrics have different units and noise levels. Deltas require a stated reference interval and normalization before matrix multiplication gives a meaningful combined pressure.
241
242Click-through rate
243Image region: Panel 11: metric-definition tiles
244CTR = clicks / impressions
245Legibility: Legible
246Editorial mathematical explanation: The share of impressions that receive clicks; it requires a nonzero impression count.
247
248Cost per click
249Image region: Panel 11: metric-definition tiles
250CPC = cost / clicks
251Legibility: Legible
252Editorial mathematical explanation: Average spend per click over a common reporting window; it requires nonzero clicks.
253
254Cost per thousand impressions
255Image region: Panel 11: metric-definition tiles
256CPM = 1000 · cost / impressions
257Legibility: Legible
258Editorial mathematical explanation: Spend scaled to one thousand impressions; it requires nonzero impressions.
259
260Cost per acquisition
261Image region: Panel 11: metric-definition tiles
262CPA = cost / acquisitions
263Legibility: Legible
264Editorial mathematical explanation: Average spend per recorded acquisition; acquisition criteria and attribution window must be specified.
265
266Conversion rate
267Image region: Panel 11: metric-definition tiles
268CR = conversions / visitors
269Legibility: Legible
270Editorial mathematical explanation: The ratio of conversions to visitors in the selected population. The poster uses visitors rather than sessions or clicks.
271
272Revenue per click
273Image region: Panel 11: metric-definition tiles
274RPC = revenue / clicks
275Legibility: Legible
276Editorial mathematical explanation: Revenue divided by clicks over a consistent attribution interval; zero-click periods require a handling rule.
277
278Missionmatch candidate weighted score
279Image region: Panel 12: MISSIONMATCH CANDIDATE SCORING
280Score = 0.25 Clearance + 0.25 Skills + 0.15 Certifications + 0.15 CustomerExp + 0.10 Experience + 0.10 Location
281Legibility: Legible
282Editorial mathematical explanation: Rank candidates with six feature weights summing to one. Clearance and skills each receive a quarter of the total weight, certifications and customer experience each receive fifteen percent, and experience and location each receive ten percent.
283Editorial note: A weighted average interpretation requires comparable feature scales. These chosen weights are a ranking policy; the poster gives no measured hiring validity or complete eligibility logic.
284
285Exponentially decaying learning rate
286Image region: Supporting formulas: upper-left box, first line
287η_{t+1} = η_t exp(−β L_t)
288Legibility: Legible
289Editorial mathematical explanation: Multiply the current learning rate by an exponential factor determined by loss. If β and L_t are nonnegative, the learning rate cannot increase under this rule, and larger losses reduce it more strongly.
290Editorial note: Negative losses or β change that behavior. No lower bound or recovery mechanism is shown.
291
292Atlas memory-gradient update with unclear subscript
293Image region: Supporting formulas: upper-left box, second line
294M_{t+1} = M_t + α ∇_{[unclear subscript]} L_t
295Legibility: Gradient subscript unclear
296Editorial mathematical explanation: The printed memory state receives an additive gradient-dependent increment. The variable with respect to which the gradient is taken is not reliably legible in the small source glyph, so it remains unresolved. The plus sign would indicate ascent in the named loss if M and that gradient shared the same coordinates.
297Editorial note: The source does not establish the gradient variable, differentiability, shape compatibility or intended ascent/descent convention.
298
299Domain recurrent state through Φ
300Image region: Supporting formulas: recurrent-state box
301H_{t+1}^{(i)} = Φ(F^{(i)}(X_t) + γ H_t^{(i)})
302Legibility: Legible
303Editorial mathematical explanation: Combine a domain-specific transformation of the current state with a scaled previous domain state, then apply Φ. This is a recurrent update whose memory strength is influenced by γ.
304Editorial note: The shape and meaning of Φ and F^(i) must be defined. The neighboring scalar unity score is not automatically a valid activation for a vector or tensor state.
305
306Unity-centered proximity score
307Image region: Supporting formulas: unity-score box
308Φ(z) = 1 / (1 + |z − 1|)
309Legibility: Legible
310Editorial mathematical explanation: Assign a score of one at z=1 and decrease it as the absolute distance from one increases. For finite real z the score lies in (0,1]. It is a simple proximity function rather than a causal integrated-information calculation.
311Editorial note: The source uses Φ for several different concepts. Equal notation alone does not make this scalar score the integrated information in another equation.
312
313Hub-and-six-domain coherence average
314Image region: Supporting formulas: hub-and-domain average box
315Φ_total = (Φ_hub + Σ Φ_domain) / 7
316Legibility: Legible
317Editorial mathematical explanation: Average one hub score and six domain scores with equal weight. The adjacent Unified AGI diagram explicitly labels six domains plus a hub, which explains the denominator seven.
318Editorial note: The result is an arithmetic average of the supplied scores. It is not automatically the integrated information of the combined causal system; additivity would require separate justification.
319
320Saturating knowledge-gradient magnitude
321Image region: Supporting formulas: upper-right box
322g(t) = ‖∇H(t)‖ / (1 + ‖∇H(t)‖)
323Legibility: Legible
324Editorial mathematical explanation: Map a nonnegative gradient magnitude r to r/(1+r). It is zero at r=0, increases monotonically, and approaches one for large r, limiting the influence of very large gradients.
325Editorial note: The expression assumes compatible units or a dimensionless gradient magnitude. It does not measure consciousness independently of the chosen H.
326
327Softmax action policy
328Image region: Supporting formulas: lower-left box
329π(a|s) = softmax(Q(s,a))
330Legibility: Legible
331Editorial mathematical explanation: Convert action values into a distribution over actions by applying softmax across the available action set. Actions with larger values receive larger probability, while finite values keep every available action at positive probability.
332Editorial note: The action axis and temperature are not printed. An implementation needs a defined action set and a numerically stable normalization.
333
334One-step Q-learning update
335Image region: Supporting formulas: lower-center box
336Q_{t+1}(s,a) = Q_t(s,a) + α [ r + γ max_{a′} Q_t(s′,a′) − Q_t(s,a) ]
337Legibility: Legible
338Editorial mathematical explanation: Move the current action-value estimate toward the observed reward plus the discounted best next-state value. The bracket is the temporal-difference error, and α controls how much of that error is incorporated.
339Editorial note: Convergence depends on assumptions about the environment, exploration, learning rates and representation. This displayed rule is not evidence that the project trained a converged policy.
340
341G-family order label
342Image region: Supporting formulas: lower-right box
343G^x, x = 256
344Legibility: Legible
345Editorial mathematical explanation: The source pairs a G-family superscript with x=256. No expansion, operational definition or relationship to the nearby G^16 notation is given, so the expression is preserved as a parameter label.
346
347RAW OCR READING AID — NOT A VERIFIED EQUATION TRANSCRIPT
348The following preserves the complete Tesseract output, including recognition errors, decorative glyphs and layout artifacts. Use the manually inspected records above and the original PNG for mathematical notation.
349
350pe
351
352THE
353
354| ‘MEGAMIND Pee ATLAS.
355
356A MASTER ARCHIVE OF JOSEPH’S CORE EQUATIONS |
357
358)
359
360Jr
361
362ayy
363
364ANS
365
366=
367
368RHIANNON EQUATION
369
370(WD CONSCIOUSNESS ALGORITHM
371
3721(@
373
374C(t) O(G(t) - IVA (OI
375
376P* = argmin[ B(P’, D) + AC(P’-P)]
377
378a
379
380BS
381
382Fo
383
384yo-¥ f |
385
3861+IIVH@Il
387
388|e
389
390‘Comple(P’) | | TypeSate(P’)
391
392Tests(P", D)
393
394|
395
396Safety(P*)
397
398a
399
400SS
401
402[
403
404<P
405
4061
407
408Qi
409
410i
411
412\
413
414W = f(A-X-S)
415
416|
417
418|
419
420Peri = R(Pe, De)
421
422Consciousness emerges from agency, coherence,
423
424|
425
426integration, field pressure, and substrate scale.
427
428R(S
429
430Leer Se(Se(2))
431
432RHIANNON = S7(57(x))
433
434pl
435
436N
437
438\
439
440Bounded recursive code repair and self-extension.
441
442Y
443
444NN
445
446EPONA / ECHAD
447
448( s UNIFIED LEARNING
449
450|
451
452axe
453
454-Vx [F(
455
456-AV(X)]
457
458Soda
459
460= D(x) + N(x) + F(x, t) + T(x, t)
461
462Ws
463
464dt
465
466|
467
468|
469
470KX AsoG Phe «
471
472a
473
474ea
475
476ean
477
478Learning as diffusion, emergence, external force,
479
480= -V [L(X,) -AV(X)]
481
482and transport
483
484Value-directed state evolution.
485
486we
487
488li Nx
489
490=
491
492NN
493
494(Gy RESHIT SURPRISE
495
496.)
497
498HABRIT FEDERATION BINDING
499
500Aa
501
502= resolve(G'8, M'S, Al, 1S, $16, pis
503
50416)
505
506ay
507
508Q. = argmin [S(X,) + U(X,) - V(X.)
509
510=(G, M, A, V, S, P, R, N, D, T)
511
512les
513
5144\\
515
516H’® = 16-domain recursive AGI family lattice
517
518eS
519
520BEDOK).
521
522Choose the path that reduces surprise and
523
524(1.0) + 15(0.307) ~ 10.6
525
526Rep
527
528uncertainty while increasing value.
529
530N
531
532Bind intelligence domains into one coherent federation state.
533
534STDP LEARNING
535
536(@) GOLDEN RATIO KNOWLEDGE
537
538“\
539
540u(x) = sin(2z- g* -0;-x) + cos(2x- $* -;-x)
541
5422b
543
544t
545
546Awy = 1 (Ci) (tyre ~ tyes) exP (=
547
548)
549
550) = > Oe(h(q))
551
552Ae
553
554Timing, coherence, integration,
555
556Knowledge reconstructed through
557
558golden-ratio harmonic bases.
559
560and decay shape neural learning
561
56247S
563
564oN
565
566EXTERNAL FEDERATION OBJECTIVE
567
568LATTICE PROJECTION
569
570Jeotat = Utility + Sse + Rgoat + Bnovet ~ Penalties ~ Risk ~ Resource
571
5721(S) > X
573
574G
575
576J(a\s)
577
578U(a,5) + Ssem(4s 8) + Reoat(4, $) + Bnovei(4, 8)
579
5809)
581
582~ Prepear(@) ~ Prai(S) ~ Prauack(s)
583
584Risk(a) - Cost(a)
585
586523M _, 5000
587
588Soom = Wetae-AState + WarfactAtifact + Wingo info_gain + weoa-goal_progress
589
590repeat = Arep * log(1 + ma)
591
592eta = Actatt stalled_cycles
593
594Xj inj = jeR
595
596a
597
5982
599
600atoack = Arp * fallback_count
601
602ae
603
604B®
605
606‘Autonomous action selection under progress, novelty,
607
608‘Map the live substrate into the 5000-dimensional
609
610penalties, risk, and cost
611
612-
613
614experiential lattice
615
616\
617
618A
619
620@) ? MARKETING INTELLIGENCE
621
62212) MISSIONMATCH CANDIDATE SCORING
623
624We41 = softmax(log(w,) + B(Pd,))
625
626Score = 0.25 Clearance + 0.25 Skills
627
628YS
629
630[ACTR, -ACPC, -ACPA, ACR,
631
632+ 0.15 Certifications + 0.15 CustomerExp
633
634ARPC, ~ABounceRate, A Engagement }
635
636CTR
637
638crc
639
640CPM
641
642CPA
643
644cR
645
646RPC
647
648+ 0.10 Experience + 0.10 Location
649
650clk /
651
652lds
653
654cont!
655
656|
657
6581000 ost /
659
660coat)
661
662conven!
663
664wll.
665
666renoce/|
667
668i
669
670=
671
672impressions
673
674impresons
675
676acqisions
677
678‘Weighted candidate ranking
679
680|@
681
682Ne
683
684Adaptive marketing weights driven by performance signals.
685
6862X
687
688for mission fit.
689
690=
691
692=
693
694x
695
696—
697
698Y
699
700S
701
702SUPPORTING FORMULAS &
703
704a
705
706\¢
707
708Test = Ne exp(—BLi)
709
710Ho,
711
7121
713
714otal =
715
716ta Dn
717
718(t) =
719
720IVH())
721
722eat = Me + aV pL
723
724(F(x,) +H) J, (2) =
725
726T+ke= 2-1)
727
728\
729
730i WHOM
731
732s
733
7342K
735
7364
737
738, ¢
739
740(als) = softmax(Q(
741
742))
743
744[ Ql) = = 6.0) +ar+y max Q(0)- O(a]
745
746Gtx = 256 / 1-156 @
747
748=
749
750THE SYSTEM EVOLVES THROUGH CONSCIOUSNESS, LEARNING, REPAIR
751
752VALUE, FEDERATION, PROJECTION, AND ADAPTIVE INTELLIGENCE.
753
754J
755
756